cetis blogs

Skip to content
  • Cetis Blogs Home
  • About Cetis Blogs
  • Cetis sites
    • Cetis home
    • Cetis blogs
    • Cetis publications
Archived content.
See the Cetis home page for our current site.

Category Archives: metadata

LRMI Implementation Case Study: Gooru

Posted on August 14, 2014 by Lorna Campbell

Project lead: Lisa McLaughlin,  Senior Director of Partnerships

“Gooru’s mission is to honor the human right to education. We are dedicated to engaging a community of teachers, developers, and supporters to unleash personalized learning with technology to educate all the students of the world.”

http://www.goorulearning.org/

Gooru serves as a personalized learning platform, incorporating a custom search engine, playlist creation tool, and content aggregator.  The system allows users to find standards-aligned, interactive learning materials that have been curated by teachers; share those materials in the form of custom collections, personalized to meet the needs of individual students; and measure students’ progress across collections and quizzes assigned to them.  Users can search over 2 million CC licensed learning resources, browse through collections, lessons and individual resources and filter search results by grade level, resource type, and Common Core State Standard.

Gooru resource search

Gooru resource search

Gooru is a repository of playlists, rather than a repository of content.  There are currently 18 million resources in the Gooru catalog; 180,000 of these are tagged to instructional standards such as the Common Core State Standards and 50,000 are collections created by teachers and students. Users can also build assessment features into their playlists and the system includes an assessment bank of 1.5 million items. Gooru resources carry a variety of different licences but all are open and free to use. Playlists are currently shared under a CC BY SA licence, however Gooru are in the process of transitioning to CC0 over the course of the next month.  Most content is aimed at the K-12 sector.

Gooru collection search showing CCSS classification

Gooru collection search showing CCSS classification

Gooru has developed an open source learning architecture licensed under the MIT Open Source Initiative approved licence, and a number of APIs that enable developers to build applications based on the Gooru infrastructure. The Gooru APIs are available here: Gooru APIs, and further information about the Gooru development community is available here Gooru Learning Developers.

A custom Gooru Metadata Schema (GMS) composed of 40 fields has been created from various metadata schemas. The Gooru Metadata Schema may be regarded as a variant of the LOM, though to date, GMS has not been mapped directly to LOM. Accessibility Metadata Project fields are used to describe the accessibility of content.

Content with high quality metadata is weighted more heavily in search results, though other factors also come into play, such as how many times a resource is included in other playlists.

Gooru does not ingest metadata through OAI PMH; some metadata is generated by users uploading resources and tagging them using the GMS, but the majority comes from web crawling. Domains are curated through a range of input, both internal and through Gooru’s wider network of partners, before pursuing crawls. Teacher-added domains are prioritized.  Basic metadata including title, author, publisher, description, etc is captured from each domain, and then passed to a QA cleaning team, who manually identify more nuanced characteristics, e.g. educational use, time required, etc. For subjective fields, such as educational use, a script has been created for cleaning the metadata. The QA team is currently focused on cleaning the metadata on all OER collections and Gooru recently launched an OER filter.

Metadata fields are currently stored in an SQL database, however Gooru will move to a no-SQL framework later in 2014.  Paradata is also  stored in similar SQL tables but is returned by different APIs. Only some of the Gooru paradata is currently exposed.

Components of LRMI have been incorporated into the Gooru Metadata Schema and a mapping can be provided from the GMS to LRMI.  Approximately 95% of the Gooru catalog is now tagged with LRMI.

The following LRMI properties and types have been implemented and the Gooru LRMI Metadata schema is available here (.xls).

  • educationalAlignment
  • educationalUse
  • timeRequired
  • typicalAgeRange
  • interactivityType
  • learningResourceType
  • useRightsUrl
  • isBasedonUrl

The GMS includes an Educational Alignment field with alignment types ‘subject’ and ‘educational level’.  Alignment type ‘text complexity’ may be added in the future.

In addition to Common Core State Standards, Gooru content is also aligned to  Texas Curriculum Standards and California Science Standards

Links

Gooru
Gooru Metadata Guide
Gooru LRMI Metadata Schema


Posted in cetis, lrmi, metadata, oer

LRMI Implementation Case Study: Jorum

Posted on August 7, 2014 by Lorna Campbell

Project lead – Ben Ryan, Jorum Technical Coordinator.

“Jorum is a Jisc funded Service for UK Further and Higher Education, to collect and share open educational resources, allowing their reuse and repurposing. Jorum’s free online repository service forms a key part of Jisc’s Learning and Teaching digital content offering. It is the first port of call for thousands of resources, all shared and created by those who teach or have been inspired in the FE and HE and professional skills community.”

http://www.jorum.ac.uk/

The Jorum LRMI implementation project began in September 2013 and work is ongoing as the platform develops. Jorum is a DSpace repository containing a wide range of educational resources in many different formats, including a considerable volume of IMS Content Packages. The repository contains approximately 16,000+ resources, most of which are openly licensed. Jorum uses a combination of LOM, DC, LRMI, Jorum metadata, plus custom fields for different collection ‘windows’. LRMI properties are crosswalked to LOM education fields.

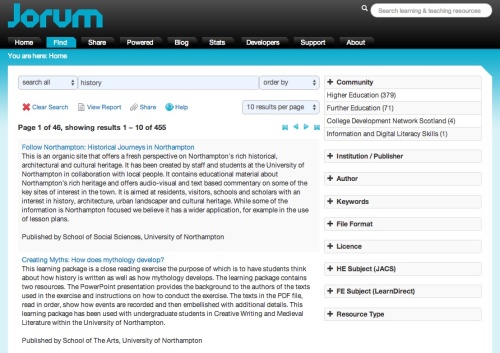
jorum_search_results

Jorum search returns page

Implementing LRMI in Jorum presented something of a challenge to the project team as DSpace only allows metadata to be added to ‘items’ which are collections of individual files.  Metadata can not be applied at the file level, e.g. an html page within a content package, and there is no way to add microdata to an individual page. If Jorum ingests a resource that already includes LRMI it can be cross walked to map to the LOM fields, however if a content package contains multiple pages that are marked up with LRMI it is difficult to extract this data as there is nowhere to store it in DSpace.  In addition, in order to enable a search engine to access a full set of LRMI metadata it is necessary to generate a page containing the LRMI which the search engine can hit. The default page generated by DSpace only includes title, author and description. To generate a page with a richer set of metadata it is necessary to create a custom theme, which is a non trivial task.

jorum_record_2

Jorum resource page

Despite the technical difficulty of implementing LRMI in DSpace, the Jorum project has made good progress and the team have plans for further development in this area including implementing the new Schema.org License property, implementing the alignmentObject and aligning it to the UK higher education Joint Academic Subject Coding Scheme.  The project team also plan to build a Google Custom Search engine to demonstrate how Jorum LRMI metadata can be surfaced.

Jorum has implemented the following LRMI properties and types, though this is dependent on what metadata has been supplied for each resource.

  • educationalAlignment: plan to implement in the future
  • educationalUse: yes,
  • timeRequired: yes
  • typicalAgeRange: no
  • interactivityType: yes
  • learningResourceType: yes
  • useRightsUrl: no, but plan to implement License property

The Jorum project team have not yet shared their LRMI metadata with the Learning Registry as they are waiting to upgrade their platform to DSpace 4.0 before taking this implementation forward as DSpace 4.0 includes an upgraded OAI PMH interface providing a good flexible way to generate metadata from different schema.  It should be noted that Jorum have already undertaken a successful Learning Registry implementation project, the Jisc funded JLeRN Experiment ( which successfully built a Learning Registry node in the UK and developed a number of prototype services for LR ingest and querying. The same developer responsible for the JLeRN implementation has been commissioned to undertake the Jorum LRMI implementation and this work will be taken forward once the upgrade to DSpace 4.0 is complete.

Links

Jorum
Jorum Case Study Questionnaire
Jorum Blog: Implementing the Learning Resource Metadata Initiative (LRMI) in Jorum


Posted in cetis, discoverability, higher education, Jorum, lrmi, metadata, oer

LRMI Implementation Case Study: Open Tapestry

Posted on August 6, 2014 by Lorna Campbell

Project team: Justin Ball, CTO;  Joel Duffin, CEO

“Open Tapestry is all about discovering, adapting, and sharing learning resources, whether you’re a teacher, an instructor, a professor, a corporate trainer, a learner, or just a curious mind! We help you organize your content into categories–or Tapestries–that you create. Open Tapestry’s toolset allows instructors to develop course materials in a fraction of the time, while invigorating and enhancing learners’ experience. We give you the tools to mold and shape content already on the web to exactly how you want it.”

http://www.opentapestry.com/

open_tapestryOpen Tapestry provides tools to enable users to author resources and create and share modules, or tapestries, from existing content.  The system also has some repository-like  aspects in that it searches open content repositories, harvests metadata and enables users to upload resources. Open Tapestry pulls in all types of resources at different levels of granularity. There are currently around a million resources, mostly aimed at higher education, however Open Tapestry has also worked with online high schools and a few primary grades.  While Open Tapestry encourages use of open content, but users are also able to create closed instances for their own organisations.

Open Tapestry is a custom platform built on Ruby on Rails.  The platform uses a number of open source libraries and about ten APIs, but is not currently open source itself. The code used to detect and parse open licences is based on Open Attribute, and Gem is used to interact with Canvas.

Open Tapestry supports IMS LTI to facilitate learning management system integration.  This allows users to manage content outside the LMS and then present it inside the system.

Open Tapestry harvests metadata using OAI PMH, web crawlers and RSS harvesters.  The application tries to be as inclusive as possible; any format of metadata that is found, e.g. Dublin Core, LOM, LRMI,  will be parsed and stored internally. This internal metadata can then be transformed into any number of other formats.  The system also facilitates some cross walking.  All harvested metadata is retained and users are able to add to that metadata.  A small number of vocabularies are built into the system, e.g. licence.

The metadata that exists for any given resource depends on what has been harvested, or created by users, however if a page has no metadata, Open Tapestry will produce basic fields used for indexing and searching.  Open Tapestry has two main levels of content granularity;  resources and collections (tapestries) and metadata is applied at both of these levels. Collections can be combined from multiple sources and metadata is provided for each source.

Open Tapestry has fields for all LRMI elements but to date, users have tended not to fill them in.

  • educationalAlignment
  • educationalUse
  • timeRequired
  • typicalAgeRange
  • interactivityType
  • learningResourceType
  • useRightsUrl
  • isBasedonUrl

One way to encourage greater adoption of LRMI suggested by Open Tapestry is to focus on providing targeted search for a particular audience or usecase e.g. learning management systems.  LMS are currently grappling with how to integrate openly licensed resources with closed content and LRMI could potentially provide a solution to this problem.

Open Tapestry does not share metadata records with the Learning Registry as the system is primarily a metadata aggregator, very few new metadata record are produced by Open Tapestry.

One significant issue surfaced by Open Tapestry is how to track metadata assertions as resources, and metadata records are edited and aggregated.  This is particularly important for derivative works, where it is necessary to keep track of entire genealogies of who is making the assertions recorded in the metadata.  While cataloguers are aware of the necessity of creating and maintaining high quality metadata, content creators often have low awareness of the importance of metadata until they have a problem, e.g. concerns about who carries liability for a resource or assertion. Technical solutions are required to address this problem.

Links:

Open Tapestry
Open Tapestry Case Study Questionnaire


Posted in cetis, lrmi, metadata, oer

LRMI Implementation Projects Case Studies

Posted on August 6, 2014 by Lorna Campbell

As part of our work for Creative Commons on the Learning Resource Metadata Initiative (LRMI), my colleague Phil Barker and I have been writing short case studies on a number of LRMI implementation projects that were funded between 2013 – 2014. Ten different OER platforms received small grants from the Gates and Hewlett Foundations to implement the LRMI specification and share their experiences with other developers. I’ll be posting the case studies here over the next couple of weeks and once all case studies have been completed we also plan to produce a high level technical synthesis of the projects’ outputs.

An early overview of some of the implementation projects was presented at the Cetis 2014 Conference at the University of Bolton in June.

LRMI Implementation Projects

Connexions / OpenStax CNX

Connexions, now OpenStax CNX, was launched in 1999 at Rice University to provide authors and learners with an open space where they can share and freely adapt educational materials such as courses, books, and reports. Today, OpenStax CNX is a dynamic non-profit digital ecosystem serving millions of users per month in the delivery of educational content to improve learning outcomes. Tens of thousands of learning objects called pages, are organized into thousands of textbook-style books in a host of disciplines, all easily accessible online and downloadable to almost any device, anywhere, anytime.

Curriki

Curriki provides peer reviewed open educational resources, curricula and instructional materials to support teachers, professional educators, students, lifelong learners, and parents, primarily in the domain of K-12 education. Curriki is a nonprofit organization and the majority of the resources is provides carry Creative Commons licences.

GooruLearning

GooruLearning an open and collaborative online learning community. Gooru enables teachers and students to find standards-aligned, interactive learning materials that have been rated by fellow teachers, share those materials in the form of personalized custom collections, measure students’ engagement, comprehension, and progress, and contribute to an active community of teachers and students by sharing your collections and best practices.

ISKME

ISKME is an independent, education non-profit company whose mission is to improve the practice of continuous learning, collaboration, and change in the education sector. ISKME supports innovative teaching and learning practices throughout the globe, and is well-known for its pioneering open education initiatives. ISKME also assists policy makers, foundations, and education institutions in designing, assessing, and bringing continuous improvement to education policies, programs, and practice.

Jorum

Jorum is a Jisc funded Service for UK Further and Higher Education, to collect and share open educational resources, allowing their reuse and repurposing. Jorum’s free online repository service forms a key part of Jisc’s Learning and Teaching digital content offering. It is the first port of call for 1000’s of resources, all shared and created by those who teach or have been inspired in the FE and HE and professional skills community.

MERLOT

MERLOT is a free and open peer reviewed collection of online teaching and learning materials and faculty-developed services contributed and used by an international education community. The MERLOT collection consists of tens of thousands of discipline-specific learning materials, learning exercises, and Content Builder web pages, together with associated comments, and personal collections, all intended to enhance the teaching and learning experience.

Open Tapestry

Open Tapestry is a toolkit that enables teachers, instructors, professors, corporate trainers, students and learners to discover, adapt, and share learning resources. The Open Tapestry toolkit allows instructors to develop course materials and organise content into categories, or Tapestries, to enhance learners’ experiences.

Peer2Peer University

Peer 2 Peer University is a grassroots open education project that organizes learning outside of institutional walls and gives learners recognition for their achievements. P2PU creates a model for lifelong learning alongside traditional formal higher education. Leveraging the internet and educational materials openly available online, P2PU enables high-quality low-cost education opportunities.

Untrikiwiki

UntrikiWiki were funded to develop a MediaWiki extension to allow the use of schema.org markup in Wikitext. As part of this project, UntrikiWiki advocated the use of open-source extension HTML Tags on wikis.


Posted in cetis, Cetis14, lrmi, metadata, oer

Explaining the LRMI Alignment Object

Posted on March 6, 2014 by Phil Barker

The educational alignment property and the associated alignment object that LRMI introduced into schema.org have been described as the “killer feature” for LRMI. However, I know from the number of questions asked about the alignment object and from examples I have seen of it being used wrongly that it is not the easiest construct to understand.

Perhaps the problems come from the nature of the alignment object as a conceptual abstraction, so maybe it will be help to show some concrete examples of how it may be used. However, bear in mind that the abstraction was a deliberate design decision made so that the alignment object should be more widely applicable than the examples given here. So I will first discuss a little about why some simpler more direct approaches were considered and rejected (as were some approaches that would be even more abstract).

Posted in lrmi, metadata

Where to put your EPUB metadata

Posted on January 15, 2014 by Phil Barker

Even in the knowledge that current mainstream EPUB readers and applications for managing eBooks will most likely ignore all but the most trivial metadata, we still have use cases that involve more sophisticate metadata. For example we would like to use the LRMI alignment object in schema.org to say that a particular subsection of a book can be useful in the context of a specific unit in a shared curriculum.

Posted in aggregated content, educational content, metadata, resource description, semantic technologies

Open Badges, Tin Can, LRMI can use InLOC as one cornerstone

Posted on July 31, 2013 by admin_cetis

There has been much discussion recently about Mozilla Open Badges, xAPI (Experience API, alias “Tin Can API“) and LRMI, as new and interesting specifications to help bring standardization particularly into the world of technology and resources involved with people and their learning. They have all reached their “version 1″ this year, along with InLOC.

Posted in ability, competences, InLOC, interoperability, metadata, standardization, Standards

ePub metadata what gets shown?

Posted on June 18, 2013 by Phil Barker

One of the issues around eTextBooks is how to describe them, specifically by way of educational metadata in ePub. That’s something that on the face of it shouldn’t be too difficult to address (at least to the extent that we know how to describe any educational resource). One thing that would be useful in demonstrating different choices for educational metadata is an app or tool that will display any metadata found in the ePub package in a sensible way. As a bit of long shot I tried four eBook readers to see whether they would; they don’t. The details follow, if you’re interested, but do let me know if you know of any tool that might be useful.

The package metadata of an ePub can include a selection of Dublin Core elements and terms. These can be refined, for example you may have two dc:title elements with refinements to specify that one is the main title and the other the subtitle. You can also extend with elements from other XML namespaces, or if you prefer you can just link to a metadata record of your favourite flavour which can be either inside the ePub package or elsewhere on the web. Any of this metadata can relate to the eBook as a whole or some part of it, e.g. a single chapter or image. Without going into details there seems to be enough scope there to experiment with how educational characteristics of the eBook might be described. [..]

Posted in cetis-content, eBooks, metadata, resource description

New Activity Data and Paradata Briefing Paper

Posted on May 1, 2013 by Lorna Campbell

Cetis have published a new briefing paper on Activity Data and Paradata. The paper presents a concise overview of a range of approaches and specifications for recording and exchanging data generated by the interactions of users with resources.

Such data is a form of Activity Data, which can be defined as “the record of any user action that can be logged on a computer”. Meaning can be derived from Activity Data by querying it to reveal patterns and context, this is often referred to as Analytics. Activity Data can be shared as an Activity Stream, a list of recent activities performed by an individual. Activity Streams are often specific to a particular platform or application, e.g. facebook, however initiatives such as OpenSocial, ActivityStreams and Tin Can API have produced specifications and APIs to share Activity Data across platforms and applications.

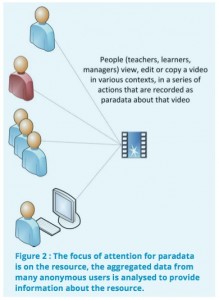
ParadataWhile Activity Streams record the actions of individual users and their interactions with multiple resources and services, other specifications have been developed to record the actions of multiple users on individual resources. This data about how and in what context resources are used is often referred to as Paradata. Paradata complements formal metadata by providing an additional layer of contextual information about how resources are being used. A specification for recording and exchanging paradata has been developed by the Learning Registry, an open source content-distribution network for storing and sharing information about learning resources.

The briefing paper provides an overview of each of these approaches and specifications along with examples of implementations and links to further information.

The Cetis Activity Data and Paradata briefing paper written by Lorna M. Campbell and Phil Barker can be downloaded from the Cetis website here: http://publications.cetis.org.uk/2013/808

Posted in activity data, activity streams, analytics, jlern, learning analytics, learning registry, learningreg, metadata, paradata

InLOC moving on

Posted on April 30, 2013 by Simon Grant

Today is the final day of the InLOC project — a European ICT Standardization Work Programme project I have been leading since November 2011. So a good day for an initial review and reflection. I blogged some previous thoughts on InLOC in November 2012 and February this year, and these thoughts are based on some aspects of the project’s final report.

InLOC — Integrating Learning Outcomes and Competences — is all about devising a good way of representing and communicating structures of learning outcomes, competence, skills, competencies, etc. that can be defined by framework owners, and used by many kinds of ICT tools, including those supporting: specifying learning outcomes of courses; claiming skills and competences in portfolios; recruitment and specifying job requirements; learning objectives relevant to resources; and possibly many more.

Project outcomes

We have produced three CEN Workshop Agreements, two formally approved and awaiting publication (Information Model, and Guidelines), and one where a workshop vote will be concluded in the coming days (Application Profile: we don’t expect any problems). Further work includes technical bindings, and two demo prototypes kindly contributed.

The Information Model

There are a number of key advances made in the InLOC Information Model, with respect to other and previous work. “LOC” here stands for “Learning Outcome or Competence”.

  1. A clear distinction is made between a LOCdefinition and a LOCstructure.
    • A LOCdefinition is similar in some ways to IMS RDCEO or IEEE RCD. Any idea of structure is kept separate from this, so that the definition can potentially be reused in different structures. Thus, a LOC definition is like the expression of just one concept about learning outcome, competence, etc.
    • A LOCstructure is the information about the structure and compound properties, but this is kept separate from any particular single definition. While it is recognised that in practice the two are often mixed, the InLOC specification separates them for clarity and for effective implementation.
  2. A clear distinction is made between defining levels with level definitions, and attributing levels (from another scheme) to definitions. This is explained in InLOC treatment of levels. This is necessary for logical clarity, and therefore at some point for applications. A decimal number is introduced as a key part of the model, to allow level information to be automatically processed.
  3. A single structural form, the LOCassociation, is used both to represent relationships between LOC structures and definitions, and to represent several different kinds of compound properties, each with more than one part. This results in structures that are easier to process, with fewer distinct information model components. It also is responsible for the relative ease of representing InLOC naturally in RDF, with minor changes to the model.

Within InLOC in general, a recurrent pattern is of one identifier together with a set of multilingual titles or labels. This is a common pattern elsewhere, and ensures that InLOC representations can naturally work multilingually.

There is a diagrammatic illustration of the Information Model structure as a UML diagram, and many more illustrative diagrams in the Guidelines section on InLOC explained through example.

The Guidelines

The central feature of the Guidelines is a detailed examination of a cross-section of the European e-Competence Framework, given as a good example of the power and flexibility of InLOC in a case from real life. The e-CF is a useful example for InLOC as it identifies 5 levels of competence. The e-CF is analysed in the section on InLOC explained through example. In this section, there are more diagrams illustrating the Information Model and how it is applied in this case.

The e-CF is fully expressed here in InLOC XML format.

Application Profile of Europass CV and Language Passport

The most used Europass instrument is the Europass CV, and Cedefop have recently been revamping it. It is a kind of simple e-portfolio, and the challenge here is to allow it to refer effectively to InLOC structures, so that the end users — the people who have the skills and competences they want to show off — can refer directly to InLOC identifiers, and so have better hope of having them accurately recognised and found in relevant searches. For the Europass CV, the InLOC team have proposed a modification of their XML Schema, and it looks like several if not all of our proposals will be taken on by Cedefop, paving the way for the Europass CV being a leading example of the use of InLOC structures in practice.

Technical bindings

No information model is complete without suggestions for how to bind it to currently relevant technologies. The ones chosen by InLOC were:

  • XML
  • RDF
  • JSON

We hope that they are reasonably clear and self-explanatory.

While the project found no great motivation for developing other bindings, I personally believe that it would be very valuable in the future to develop something with RDFa and schema.org.

Prototypes

We have been really lucky to have two initiatives filling in where the project was not funded to deliver. There is a Viewer-editors page on the project wiki with access details.

  • A team from Eummena, led by one of the team, have produced an InLOC viewer/editor based on PHP and MySQL. Here is their login page.
  • Henk Vos from Rapasso has produced a prototype using Python and Django. The interface starts here. The code is open source, GPL v3, available on GitHub.

Challenges

The main challenge in this project has been trying to generate interest and contributions from interested parties. It’s not that the topic isn’t important, just that, as usual, busy people need a pressing reason to engage with this kind of activity. This challenge is endemic to all “anticipatory” standardization work. Before either policy mandation or clear economic interest, it takes some spare effort and a clear vision before people are willing to engage.

I’m intending to write more about what this means for my own personal view of what standardization could best be, or perhaps “should” be.

Recommendations

It seems to me good practice to make some recommendations at the end of the project — after all, if one has been engaged in some good work, there should be some ways forward that are clearer at the end than at the beginning. The recommendations that the team agreed included:

  • focusing on trying to get people to publish frameworks in InLOC, as this will in turn motivate tool builders;
  • ensuring that when people are ready to adopt InLOC, they can find resources and expertise;
  • persuading developers to make it easy for users to refer to definitions within InLOC structures;
  • get other Workshop, and other European, projects to use InLOC where possible;
  • work on APIs, and on automatic configuration of key domain terms within user interfaces.
Posted in ability, competences, InLOC, metadata, portfolio, standardization, Standards

Post navigation

← Older posts
Newer posts →
Loading

  • Home
  • About Cetis Blogs
  • Cetis sites